Pairwise Testing: Definition, Example, Tools, and 6 Steps
Pairwise testing covers every pair of input values using far fewer test cases. See a hand-checkable example, tools, and steps.
Every option you add to a product multiplies the number of ways people can use it, and a checkout page with just 6 settings already has 648 of them. Pairwise testing exists because nobody can check all 648 by hand, and most teams add settings faster than they add testers.
The usual shortcut is to test a few "important" combinations and hope the rest behave. That is exactly how a bug that only appears for guest users on Safari paying with a gift card reaches production.
This guide explains what pairwise testing is, shows an example you can check by hand, compares the free tools, and walks through 6 steps, including where it fits among other test case design techniques.
What is pairwise testing?
Pairwise testing, also called all-pairs testing, is a test design technique that selects a small set of test cases in which every possible pair of input values appears together at least once. It targets bugs caused by two settings interacting, without running every full combination.
The technique starts from a plain list. You write down each parameter your feature accepts, such as browser or payment method, and the values each one can take. A test case is one row that gives a value to every parameter.
Exhaustive testing runs every possible row. Pairwise testing runs only enough rows that any two columns, read together, show every combination of their values. It is a black-box technique, so it needs no access to code. That puts it among the types of software testing that work from a spec rather than from source.
NIST Special Publication 800-142 describes it as testing "in which all possible pairs of parameter values are covered by at least one test." The same report treats pairwise as the 2-way case of a broader family called combinatorial, or t-way, testing.
The interaction rule: why covering pairs finds most bugs
The method rests on one finding from real failure data. Between 1999 and 2004, NIST studied bug reports from medical device recalls, a browser, a web server, and a NASA database. For each bug, the researchers counted how many parameters had to line up before it appeared.
The answer was very few. In the NASA data, 67% of failures were triggered by a single parameter value, 93% by 2-way combinations, and 98% by 3-way combinations. Every system studied reached 100% detection somewhere between 4-way and 6-way interactions.
NIST summarized the result as the interaction rule: "Most failures are induced by single factor faults or by the joint combinatorial effect (interaction) of two factors, with progressively fewer failures induced by interactions between three or more factors."

The browser and server curves start lower than the medical and NASA ones. That matters later, when you decide how strong coverage needs to be. The NIST ACTS project page also reports studies that found fault detection equal to exhaustive testing with a 20X to 700X reduction in test set size.
What pairwise testing promises and what it does not
Pairwise coverage promises that every value of every parameter has run next to every value of every other one. It does not promise that every triple has run. NIST is direct about the gap: pairwise testing "may miss 10% to 40% or more of system bugs, and is thus not sufficient for mission-critical software."
For a checkout page, a settings screen, or a browser matrix, that trade is usually worth making. For a payment approval path or a safety check, you raise the strength, and a later section shows how. First it helps to see exactly why the exhaustive count gets out of hand so quickly.
Why exhaustive testing fails and pairwise testing scales
Exhaustive testing grows as the product of all value counts. Pairwise testing grows far more slowly, and the gap widens with every parameter you add. One table makes the difference concrete.
The combinatorial explosion in one table
Here is the checkout page from the introduction, written out as parameters and values.
| Parameter | Values | Count |
|---|---|---|
| browser | chromium, firefox, webkit | 3 |
| viewport | desktop, tablet, mobile | 3 |
| userRole | guest, member, admin | 3 |
| paymentMethod | card, paypal, applePay, giftCard | 4 |
| shipping | standard, express, pickup | 3 |
| couponApplied | yes, no | 2 |
Multiply the counts and you get 3 × 3 × 3 × 4 × 3 × 2 = 648 test cases. Add a fifth payment method and it becomes 810. Add a currency parameter with 3 values and it becomes 2,430. Nobody budgets for that, so teams quietly stop at the handful they can afford.
Most Playwright teams already run the browser column through projects. A guide to cross-browser testing with Playwright covers that half in detail. The other five columns are where the explosion hides, because they live inside each project as data.
How the pairwise count grows instead
NIST SP 800-142 gives the growth rate. The number of t-way tests is proportional to v to the power t, times the logarithm of n, for n parameters with v values each. For pairwise, t is 2, so the count depends mostly on the largest value sets and grows only with the log of the parameter count.
Two runs show the curve. NIST's own example in SP 800-142 covers an application with 72 possible platforms using 10 tests. A model with 10 parameters of 5 values each, which has 9,765,625 exhaustive combinations, needed 47 rows when generated with PICT during the research for this post.
Every one of those rows costs CI minutes. A look at Playwright CI cost optimization shows the same suite billed very differently depending on how many tests it carries. Fewer, better-chosen rows also leave fewer places for flaky tests to hide.

Tip: Before you cut anything, put a number on what the suite costs today. The CI Budget Calculator and Flaky Cost Calculator in TestDino's free Playwright tools give you a baseline to compare against after the pairwise cut.
Seeing the multiplication is one thing. Seeing the pairwise answer, small enough to check by hand, is what makes the idea stick.
A pairwise testing example you can check by hand
Start with 3 parameters so the whole result fits on one screen: browser (chromium, firefox, webkit), viewport (desktop, mobile), and userRole (guest, member). Exhaustive testing needs 3 × 2 × 2 = 12 cases.
The pairwise version needs 6. Here is the exact set that PICT 3.7.4 generated for this model.
| Test | browser | viewport | userRole |
|---|---|---|---|
| 1 | chromium | mobile | member |
| 2 | chromium | desktop | guest |
| 3 | webkit | mobile | guest |
| 4 | firefox | desktop | member |
| 5 | firefox | mobile | guest |
| 6 | webkit | desktop | member |
How to verify that every pair is covered
Pick any two columns and list the pairs they should contain. Browser and viewport have 3 × 2 = 6 possible pairs, and the table has all 6: chromium with mobile and desktop, firefox with mobile and desktop, webkit with mobile and desktop.
Browser and userRole also have 6 possible pairs, and all 6 appear. Viewport and userRole have 4, and rows 1 through 4 cover them. PICT's statistics flag reports 16 pair combinations for this model, and these 6 rows cover all 16.
The trick is that each row does triple duty. Row 3 covers webkit with mobile, webkit with guest, and mobile with guest at the same time. Good generators pack as many uncovered pairs into each row as they can. That is why it ranks among the more dependable test generation strategies for features with many inputs.
The same example at 6 parameters
Run the full checkout model through the same generator and the 648 exhaustive cases become 16 pairwise cases. Ask for 3-way coverage and the count is 54. Ask for 4-way and it is 149. Those figures come from an actual PICT run, not an estimate.

That is a reduction of more than 97%, and the saving grows with each parameter you add. Getting those rows for your own feature means following a short, repeatable process.
How to do pairwise testing in 6 steps
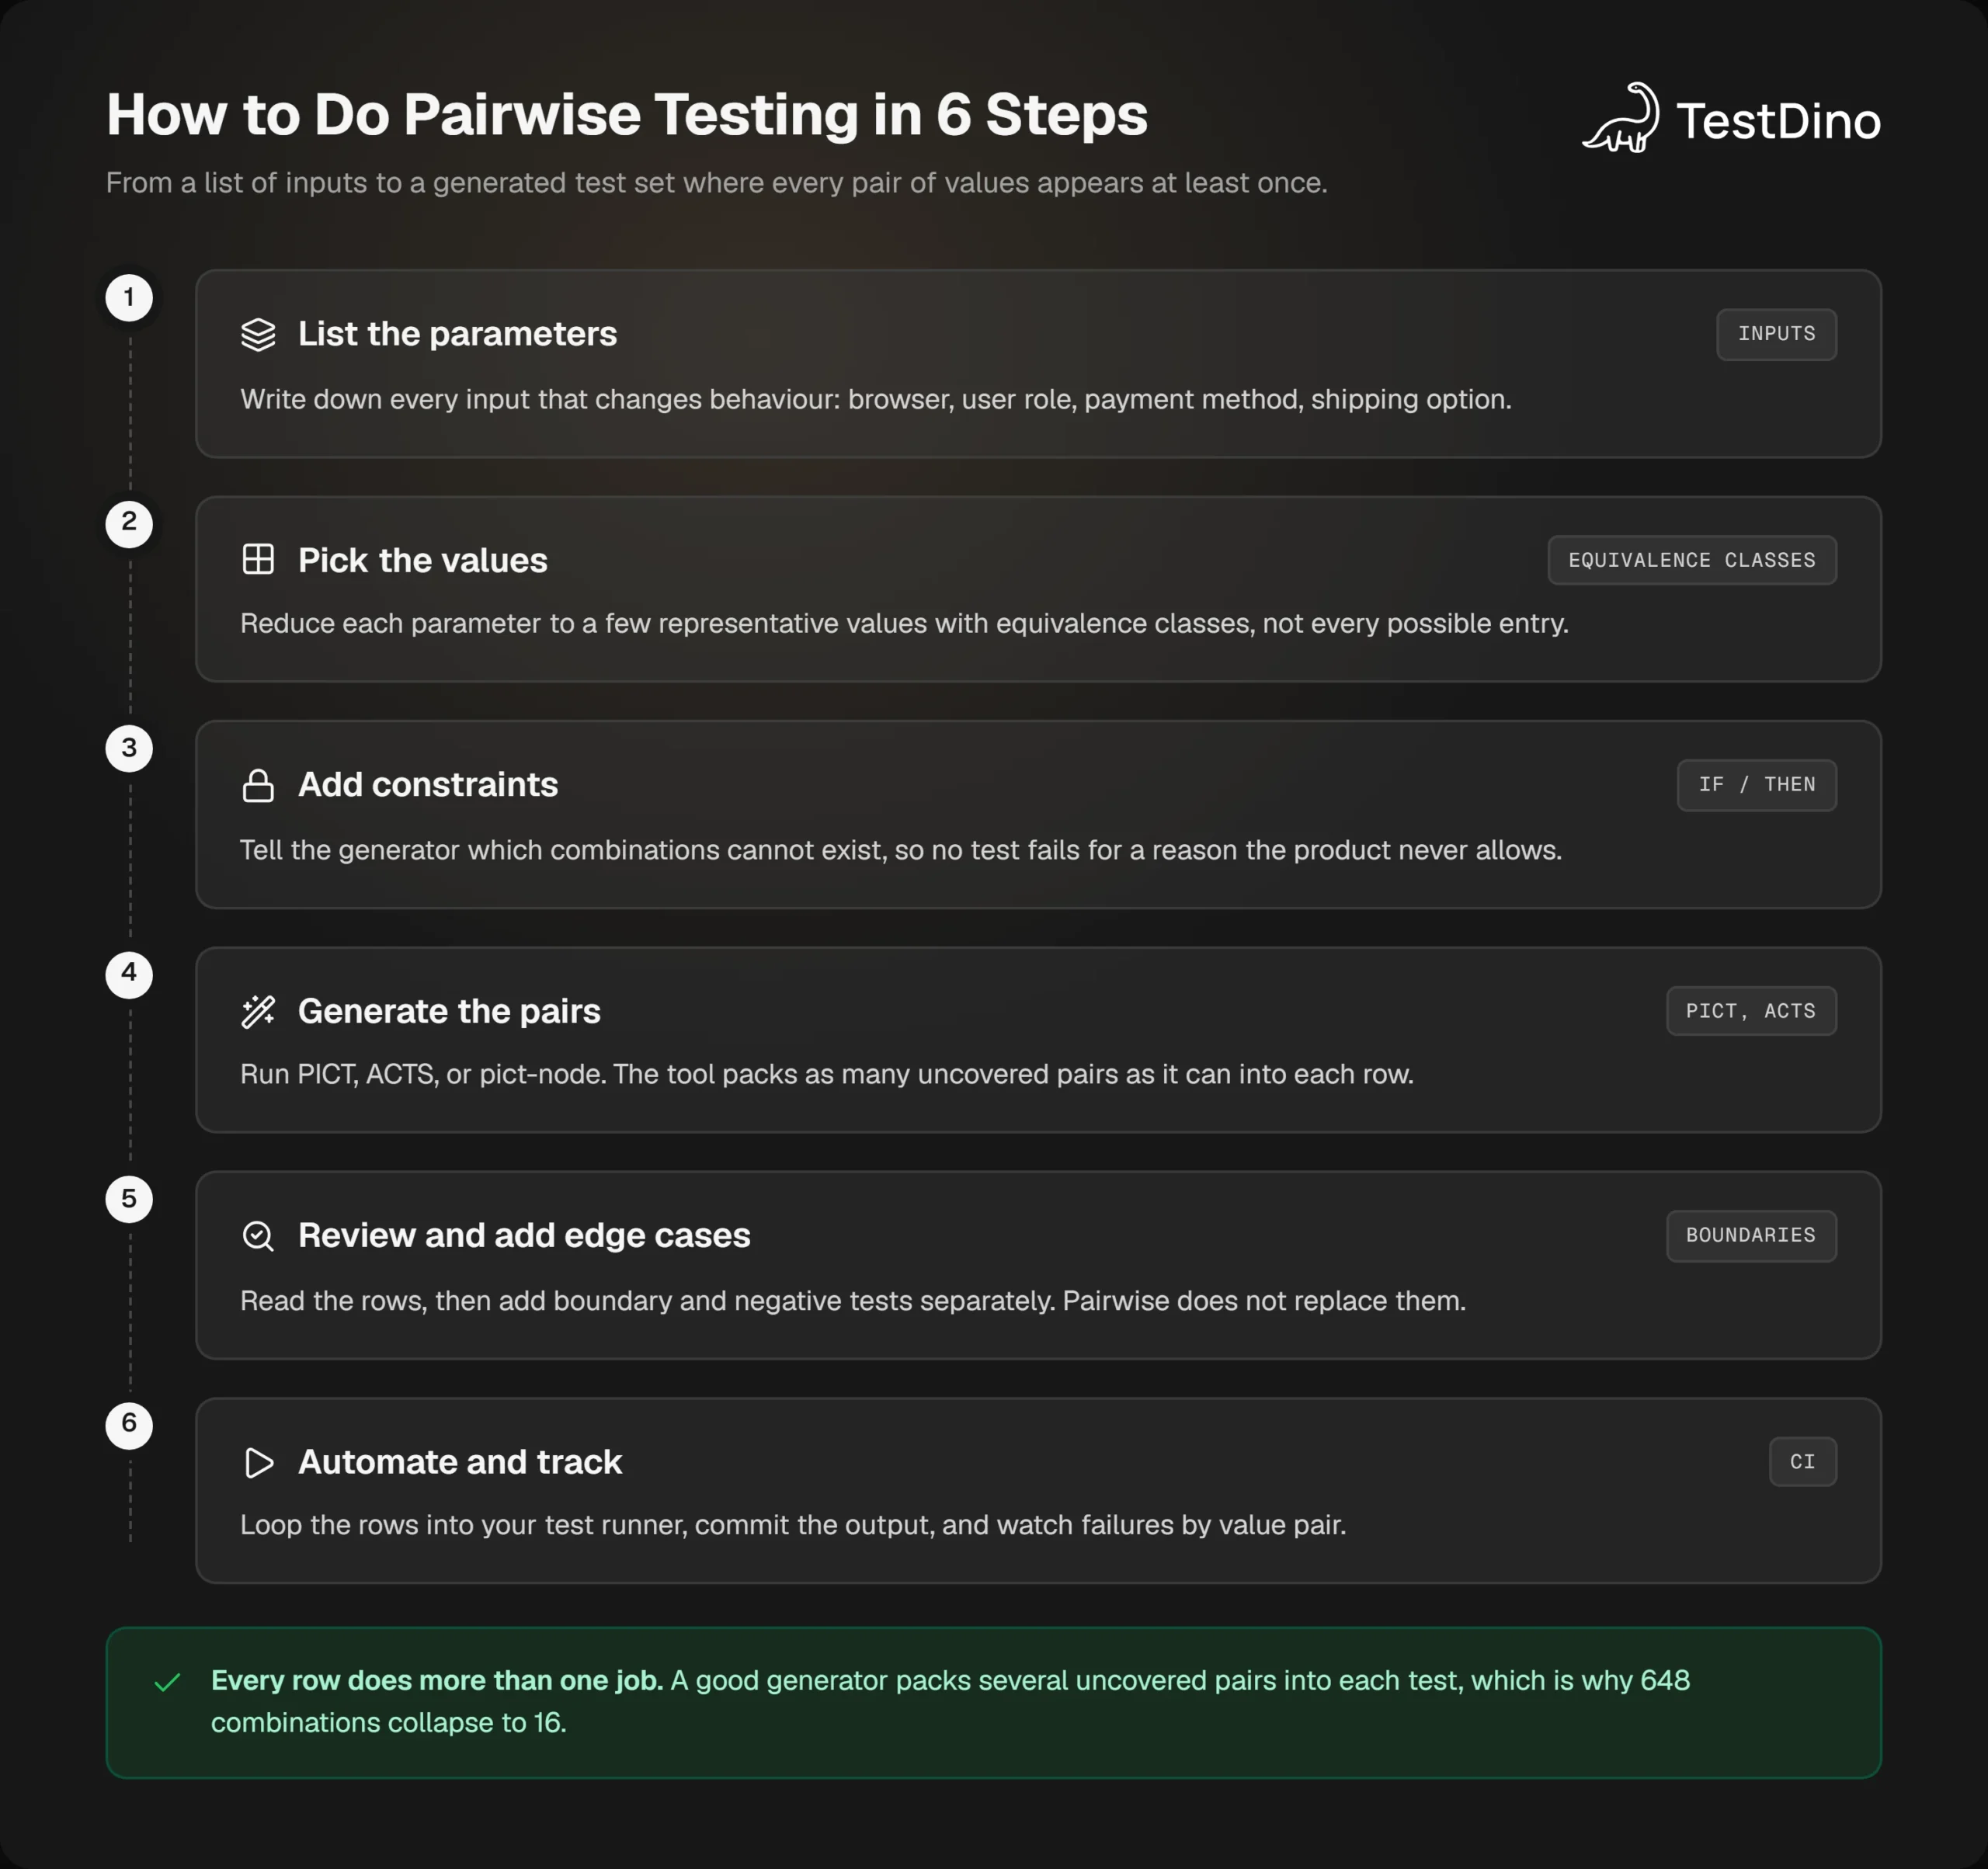
Pairwise testing follows the same 6 steps whether you work from a spreadsheet or a script:
- List every parameter that changes the feature's behaviour.
- Choose a small set of representative values for each parameter.
- Write constraints for combinations the product cannot produce.
- Generate the test set with a tool such as PICT or ACTS.
- Review the rows, then add boundary and negative tests separately.
- Automate the rows, commit the output, and track failures by value pair.
Steps 1 and 2: choose parameters and values
Only include parameters that change a code path. A parameter with 12 values that all take the same route adds pairs without adding coverage, so group values into equivalence classes first. NIST warns in SP 800-142 that if the chosen classes do not truly represent a parameter's range, some flaws will slip through.
Keep the values realistic. If your team already feeds data-driven tests in Playwright from a JSON file, that file is usually the best place to find the values customers actually use.
Step 3: write the constraints
Without constraints, a generator will happily produce Apple Pay on Firefox or a coupon for a guest. Those rows fail for the wrong reason. They get marked as known failures and teach the team to ignore red. The PICT model syntax expresses them as IF and THEN lines.
browser:        chromium, firefox, webkit
viewport:       desktop, tablet, mobile
userRole:       guest, member, admin
paymentMethod:  card, paypal, applePay, giftCard
shipping:       standard, express, pickup
couponApplied:  yes, no

IF [browser] <> "webkit" THEN [paymentMethod] <> "applePay";
IF [userRole] = "guest" THEN [couponApplied] = "no";
Steps 4 to 6: generate, review, automate
pict checkout.pict > checkout.pairwise.tsv
pict checkout.pict /o:3 > checkout.3way.tsv
pict checkout.pict /s
The first command writes the pairwise rows. The /o:3 flag raises the strength to 3-way, and /s prints statistics, including how many pair combinations the model contains. With the two constraints above, the model has 131 valid pairs, and PICT covered them in 17 rows.
Review the rows before automating them. Pairwise testing covers interactions between valid values, so boundary values and invalid inputs still need their own tests. Then loop the rows into your runner, which the Playwright section below shows in full.
Note: PICT does not promise the smallest possible suite. Its documentation states that "different random seed values will often produce a different number of total test cases." Running the constrained checkout model with 10 different seeds gave 16 rows for 7 of them and 17 for the other 3. Commit the output you choose, so CI never silently changes which combinations run.
Step 4 names a tool, and the choice between them is simpler than the long lists on other sites suggest.
Pairwise testing tools compared
You do not need to write the pair-packing algorithm yourself. The pairwise.org tools list catalogs 59 generators, but 3 free ones cover almost every team.
| Tool | Maintainer | License | How you use it | Constraints | Strength |
|---|---|---|---|---|---|
| PICT | Microsoft | MIT | Command line, plain-text model file | Yes, IF and THEN syntax | Any order via /o:N |
| ACTS | NIST | Free, public domain | Java GUI or command line | 2-way to 6-way in NIST's examples | |
| pict-node | Community | MIT | npm package wrapping PICT | Yes, via the strings() function | Any order via the order option |
PICT on the command line
PICT takes a text file with one line per parameter and prints one test per row. The documentation states that by default it "generates a pair-wise test suite (all pairs covered)", and the latest release at the time of writing is 3.7.4.
Three options matter most. The /o:N flag sets the order, /r randomizes generation with an optional seed, and /e points to a seeding file that pins rows you always want present, such as a known regression. Sub-models, covered later, let one group of parameters use a different order from the rest.
pict-node for JavaScript projects
If you would rather keep everything in TypeScript, pict-node wraps the same engine. Its install script downloads the PICT 3.7.4 binary on Windows. On Linux and macOS it clones the PICT repository and compiles it, so those machines need git, make, and a C++ compiler.
npm install --save-dev pict-nodeTwo functions matter. The pict() function accepts values of any type and returns typed objects. The strings() function accepts only string values but supports constraints, so it is the one to use for a model like the checkout page.
Teams comparing this with an automated test case generator should note that pairwise generation is plain math with a fixed result, not AI guessing.
How much the tool choice changes the count
The efficiency comparison on pairwise.org runs each generator against the same reference models. For a model with 15 parameters of 4 values, 17 of 3, and 29 of 2, the published counts are close together.
| Tool | Tests generated |
|---|---|
| CoverTable | 28 |
| TestCover | 29 |
| AllPairs (McDowell) | 34 |
| PICT | 37 |
| Jenny | 38 |
The spread is 10 rows on a model whose exhaustive count has 26 digits. Pick the generator that fits your pipeline and supports constraints, not the one that saves a few rows. Whatever produces the rows, the next question every team asks is whether pairwise is strong enough, or whether some parameters deserve more.
Pairwise vs exhaustive vs 3-way vs orthogonal array testing
Coverage strength is the t in t-way testing. Pairwise is t = 2. Raising t covers more interactions, costs more tests, and is the standard answer when pairwise misses something. The checkout model shows the price of each step up.
| Strength | Guarantee | Rows for the checkout model |
|---|---|---|
| Pairwise (2-way) | Every pair of values appears at least once | 16 |
| 3-way | Every triple of values appears at least once | 54 |
| 4-way | Every 4-value combination appears at least once | 149 |
| 5-way | Every 5-value combination appears at least once | 335 |
| Exhaustive (6-way) | Every full combination | 648 |
When to raise the strength to 3-way
NIST SP 800-142 suggests a simple heuristic: "start testing using 2-way (pairwise) combinations, continue increasing the interaction strength t until no errors are detected by the t-way tests". In the NASA data, the jump from 2-way to 3-way moved detection from 93% to 98%. In the browser data on the chart earlier, the same jump moved it from 76% to 95%.
That gap is the decision rule. For a UI flow where most bugs come from one bad value or an obvious clash, pairwise is enough. For a pricing engine, a permissions matrix, or a mobile setup with many device profiles, 3-way on the sensitive parameters is cheap insurance.

Orthogonal arrays vs all-pairs
Older textbooks teach pairwise through orthogonal arrays, and the two are often confused. NIST SP 800-142 draws the line. In an orthogonal array, every combination of t values occurs the same number of times. A covering array only requires that each one appears at least once.
The covering array is what PICT, ACTS, and every all-pairs tool build. NIST notes that it "may result in some test duplication" but can be computed for much larger problems than an orthogonal array. For a model with uneven value counts like the checkout page, with 3, 3, 3, 4, 3, and 2 values, an all-pairs generator is the practical choice.
Mixed strength with sub-models, and a trap to avoid
PICT sub-models let you wrap a group of parameters in braces and give that group its own order. The intent is to test a risky group more deeply while the rest stays pairwise.
browser:        chromium, firefox, webkit
viewport:       desktop, tablet, mobile
userRole:       guest, member, admin
paymentMethod:  card, paypal, applePay, giftCard
shipping:       standard, express, pickup
couponApplied:  yes, no

{ userRole, paymentMethod, couponApplied } @ 3
Here is the trap. That group has exactly 3 parameters, so order 3 means all 24 of its combinations must appear. PICT then treats the group as one compound value and pairs it with the other parameters. The result in the research run was 72 rows. Plain 3-way across all 6 parameters needed only 54.
Sub-models pay off when the group is large compared with its order, for example 6 parameters at order 3. When the group is small, plain /o:3 is cheaper and covers more. Compare the counts before you choose. Once the strength is settled, the remaining work is wiring the rows into a real test runner, and Playwright makes that short.
Pairwise testing in Playwright: from generated rows to named tests
The plan is simple. A small script owns the model and writes a JSON file, and a spec file loops over that JSON. The JSON is committed, so CI never regenerates tests, and every change to the model shows up as a reviewable diff.

Generate and commit the cases
Keep the model in one file so it is the single source of truth. The constraints are the same two lines from the PICT model earlier, passed as strings.
import { strings } from "pict-node";
import { writeFileSync } from "node:fs";

const model = [
  { key: "browser", values: ["chromium", "firefox", "webkit"] },
  { key: "viewport", values: ["desktop", "tablet", "mobile"] },
  { key: "userRole", values: ["guest", "member", "admin"] },
  { key: "paymentMethod", values: ["card", "paypal", "applePay", "giftCard"] },
  { key: "shipping", values: ["standard", "express", "pickup"] },
  { key: "couponApplied", values: ["yes", "no"] },
];

const constraints = [
  'IF [browser] <> "webkit" THEN [paymentMethod] <> "applePay";',
  'IF [userRole] = "guest" THEN [couponApplied] = "no";',
];

const cases = await strings({ model, constraints });
writeFileSync("tests/checkout.pairwise.json", JSON.stringify(cases, null, 2));
console.log(`Generated ${cases.length} pairwise cases`);node scripts/generate-pairwise.mjs
# Generated 17 pairwise casesCommitting the output is the part teams skip, and it is the part that keeps CI stable. Generating at test time would let a new PICT version or a different seed silently change which combinations run.
Loop the cases into tests
Playwright's parameterize tests guide shows a plain loop that calls test() once per record and notes that test names must be unique. Putting every value in the title satisfies that rule. It also means a failure tells you the exact combination without opening a trace.
import { test, expect } from "@playwright/test";
import cases from "./checkout.pairwise.json";

const viewports = {
  desktop: { width: 1280, height: 800 },
  tablet: { width: 820, height: 1180 },
  mobile: { width: 390, height: 844 },
};

for (const c of cases) {
  test.describe(`[${c.browser}]`, () => {
    test.use({ viewport: viewports[c.viewport as keyof typeof viewports] });

    test(
      `checkout | ${c.viewport} | ${c.userRole} | ${c.paymentMethod} | ${c.shipping} | coupon=${c.couponApplied}`,
      { tag: "@pairwise" },
      async ({ page }) => {
        await page.goto("/checkout");
        await page.getByLabel("Payment method").selectOption(c.paymentMethod);
        await page.getByLabel("Shipping").selectOption(c.shipping);
        if (c.couponApplied === "yes") {
          await page.getByRole("button", { name: "Apply coupon" }).click();
        }
        await expect(page.getByTestId("order-total")).toBeVisible();
      }
    );
  });
}
Playwright collects every row at load time, and test.use() inside the describe block sets the viewport per group. Running the list command against this file during research produced 17 tests in 1 file, one per generated row.
npx playwright test --list
# checkout.spec.ts:13:9 › [chromium] › checkout | tablet | guest | giftCard | standard | coupon=no
# ...
# Total: 17 tests in 1 file
Login state for each userRole belongs in a fixture rather than in the loop. A walkthrough of Playwright fixtures shows how to make the role a fixture option. The browser column needs one more step.
Tip: With 17 tests instead of 648, you may no longer need to shard this file at all. Check the Sharding Calculator in TestDino's free tools first, and only split the suite the way the "Playwright sharding" guide describes when it still misses your CI time target.
Route browsers and run in CI
The model already contains a browser value, so do not also multiply the file across three browser projects. Give each project a grep that matches its own describe title, and chromium only runs rows generated for chromium.
import { defineConfig, devices } from "@playwright/test";

export default defineConfig({
  projects: [
    { name: "chromium", use: { ...devices["Desktop Chrome"] }, grep: /\[chromium\]/ },
    { name: "firefox", use: { ...devices["Desktop Firefox"] }, grep: /\[firefox\]/ },
    { name: "webkit", use: { ...devices["Desktop Safari"] }, grep: /\[webkit\]/ },
  ],
});
The @pairwise tag lets you run or exclude the generated group with --grep, the same mechanism covered in the guide to Playwright annotations. In CI, the group runs like any other job in your Playwright GitHub Actions setup.
The setup above produces a working suite. Keeping it honest over time depends on knowing what the technique can and cannot do, and on avoiding a few habits that quietly undo it.
Advantages, limitations, and 5 mistakes to avoid
Pairwise testing has clear strengths and clear edges. Both sides come straight from the data and the tools covered above.
| Advantages | Limitations |
|---|---|
| Cuts the suite by orders of magnitude, from 648 cases to 16 in the checkout model | Misses faults that need 3 or more specific values, which NIST puts at 10% to 40% or more of bugs in some systems |
| Targets the 1-parameter and 2-parameter faults that caused 93% of failures in the NASA data | Only as good as the parameters and values you chose; a missing value is never tested |
| Generated by a tool, so the set is repeatable and reviewable as a diff | Covers valid combinations, not boundary or invalid inputs, which still need separate tests |
| Works with uneven value counts, unlike a strict orthogonal array | Ignores the order events happen in; NIST describes separate sequence covering arrays for that problem |
5 mistakes that quietly undo pairwise coverage
Most failed rollouts have nothing to do with the math. They come from how the generated cases are treated once they exist.
- Treating rows as random samples. Delete one row because it "looks similar" to another and you lose every pair that row alone was covering. Express an impossible row as a constraint and regenerate instead.
- Skipping constraints. Impossible rows fail for the wrong reason, get marked as known failures, and train everyone to ignore red.
- Multiplying browsers twice. A browser column in the model plus three browser projects turns 17 rows into 51 runs. Use the project-level grep shown above, or keep browser out of the model.
- Hiding the values. A title like "checkout case 7" sends everyone to the JSON file on every failure. Values in the title make test failure analysis faster, because failures that share two values point at the broken pair.
- Regenerating in CI. A newer PICT release or a different seed can change the rows between two runs of the same commit. Commit the output and treat the generator like a build step, in line with the broader Playwright best practices for deterministic suites.
Note: Pairwise testing does not replace boundary tests or negative tests. PICT lets you prefix a value with a tilde to mark it invalid, and its documentation warns that "two out-of-range values do not appear in the same test case", because the first one masks the second. Keep those cases separate from the pairwise set.
How to tell whether the cut worked
A pairwise cut should show up in three places: fewer tests, shorter CI runs, and no drop in the bugs the suite catches. Record the test count and total duration before and after. A Playwright test reporting setup that stores run history makes the comparison easy.
Because every value pair appears at least once, a broken pair produces a clear pattern: several failures that share two values. TestDino's test history views show the same generated test across runs, so a pair that starts failing after a deploy stands out.
The test quality metrics to watch are pass rate, flake rate, and time to diagnose. If the first two hold steady while the suite shrinks, the cut succeeded.
Conclusion
Pairwise testing turns an impossible test matrix into a small, generated set that still covers every pair of values. The evidence behind it is not marketing. NIST measured real failures and found that most were triggered by one or two parameters, and 2-way coverage caught 93% of failures in the NASA system studied.
The method is the same everywhere: list the parameters, pick representative values, write constraints, generate with PICT or ACTS, review, and automate. The checkout model in this post went from 648 cases to 16, and to 54 when 3-way coverage was requested for extra safety.
Start with one feature that has 4 or more parameters, model it, and compare the runtime against the ideas in the guide to reduce Playwright CI runtime. If you use an AI coding assistant, the TestDino Playwright skill already knows Playwright conventions and can scaffold the generator and spec pattern shown above.
FAQs
Savan Vaghani
Product Developer