Test Automation Strategy: The Complete Guide for QA Teams
Build a test automation strategy that actually ships quality. Covers the test pyramid, tool selection, CI/CD, and the metrics that matter.
Eventually, every software team decides to automate its tests. They choose a tool, write a few scripts and everything looks good for the first two sprints. As the codebase expands the tests start failing every other day and the team slowly loses faith in the results.
That's what it's like for most teams that jump into automation without a plan. They see it as a technical problem, not a strategic one.
That collapse is prevented by a test automation strategy. It defines what is tested, to what extent, with what tool and how results get to the right people. This guide covers how to build one, why it matters to speed and quality and what the data says about teams that get it right.
What is a test automation strategy?
A test automation strategy is a formal plan that defines the objectives, scope, tools, processes, and metrics for success for automating software testing across a team or organization. It makes the testing activities more business-oriented rather than just a technical exercise in automation.
Imagine it like the difference between buying a gym membership and actually going to the gym. One gathers dust, the other produces results.
A good test automation strategy answers four key questions:
- What do we do manually and what do we automate?
- How do we manage and maintain our test code?
- Where do tests run (local, CI, cloud)?
- When are results surfaced and for whom?
Without answers to these, you end up with tests that nobody trusts, a CI pipeline nobody checks, and engineers who bypass the suite entirely because it takes 45 minutes and fails for reasons unrelated to their change.
That collapse is prevented by a test automation strategy that aligns automation work with business value and makes it easier to secure management buy-in. The broader view of types of software testing helps contextualize where automation fits across unit, integration, API, and end-to-end testing layers, while this guide focuses on speed, software quality, and how to measure success.
Why most automation efforts fail without a strategy
Here is an uncomfortable truth: most test automation projects do not fail because of bad tools. They fail because of bad planning. Weak strategy documents often skip risk analysis, limitations, and prioritization criteria.
Common failure patterns include:
- Tool first thinking. Teams pick the most popular tool without knowing their stack, skillset or test goals.
- Automate all the things. In reality, not all tests should be automated, and teams should prioritize critical tests based on business criticality and risk instead of trying to automate everything.
- Maintenance skipped. A poorly architected suite can spend 60-70% of its effort keeping tests from breaking, rather than catching real bugs.
- No integration with CI/CD. Automation in a silo adds no value of speed . It becomes a manual job that someone runs "pre-release".
- Wrong steps. The number of automated tests is a vanity metric. It tells you nothing about whether those tests are catching bugs, or giving you confidence to release, and poor prioritization leads to poor test coverage when critical tests tied to revenue or compliance are missed.
The good news is? All this can be avoided. For every failure point, there is a simple answer within a well-built test automation strategy. Data from Test failure analysis shows that environment instability, selector fragility, and missing wait strategies are the top root causes for test failures. They're not tools problems. They're all strategic and structural issues.
That's where TestDino delivers instant value. No more manually digging through CI logs. TestDino automatically categorizes every failure by root cause so your team spends time fixing bugs instead of hunting for them.
The test pyramid: your structural foundation
Before picking a single tool, you need to understand the test pyramid. It is one of the key components of a balanced automation strategy because it decides where your effort goes.
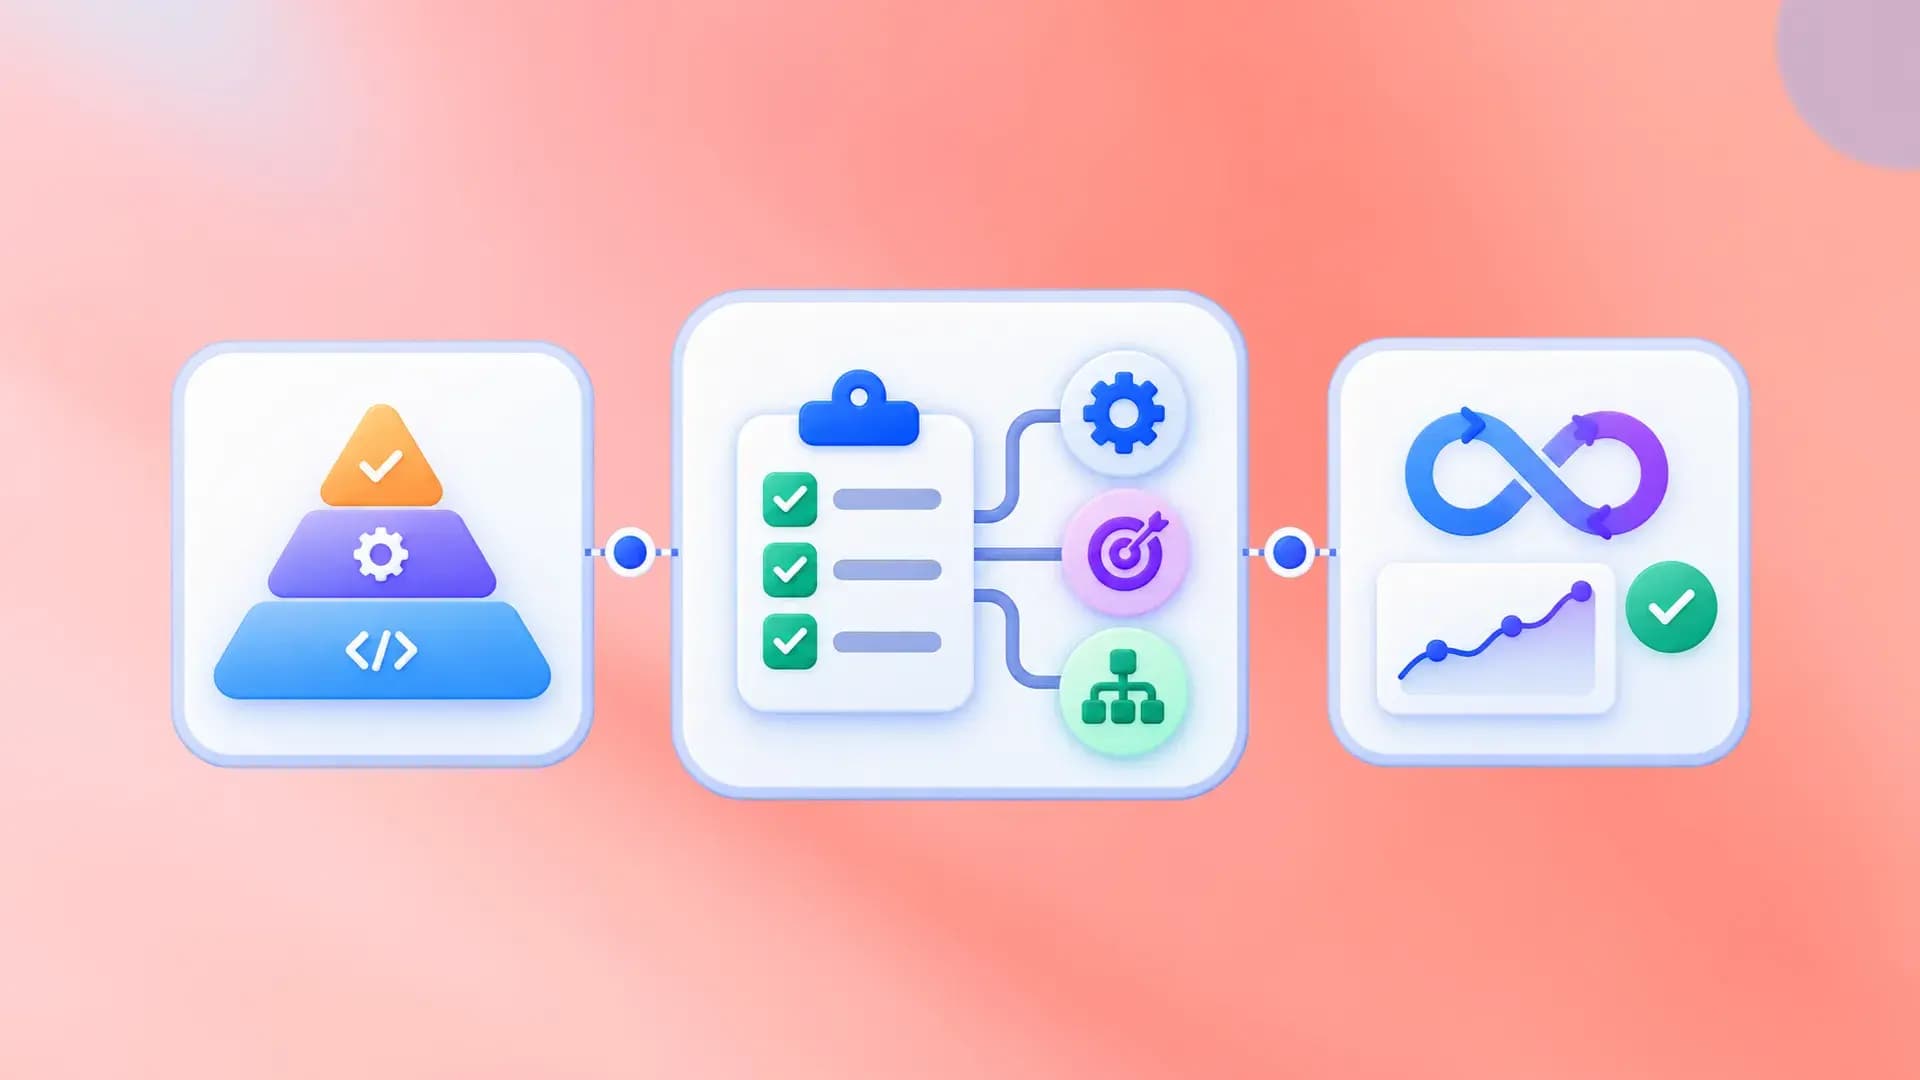
The Agile Testing Pyramid is a framework that describes how automated tests should be distributed across three layers: unit tests at the base, integration tests in the middle, and end-to-end (E2E) tests at the top. The wider the layer, the more tests you should have at that level.
The classic distribution that industry data still supports as a reasonable starting point:
- 70% unit tests -- fast, isolated, cheap to write and maintain
- 20% integration/API tests -- validate how services communicate
- 10% E2E tests -- simulate real user flows end to end
This matters in practice because here's why: teams should choose test types deliberately, with unit checks and api testing carrying most of the load.
Unit tests are run in milliseconds. When a unit test fails, the developer immediately knows what broke. There's no flakiness, no network dependency, no browser involved.
Integration tests are tests of the interaction between two or more components. They are critical in microservice architectures, as service contract mismatch may lead to silent failures undetected by unit tests.
E2E tests mimic the real user journey. They are slower, flakier, and more expensive to upkeep. Save them for your most important business paths login, checkout, signup, data submission.

Tip: Use the Agile Testing Pyramid to balance resource usage and keep testing efforts efficient. If your team has 500 E2E tests and 50 unit tests, your suite will be slow, brittle, and expensive. Invert that ratio and watch CI feedback times drop.
Modern thinking has evolved too. In AI-heavy or microservice environments, some teams advocate for a "testing trophy" shape that emphasizes integration and contract testing more. The exact shape matters less than the core principle: test at the lowest level that gives you sufficient confidence.

How to build your test automation strategy step by step
Now the practical part. A solid test automation strategy is not a 40-page document. It is a set of decisions made upfront and documented clearly.
Step 1: define your goals
Start with why. What business problem does automation solve, and what business value should it produce?
Common valid goals:
- Cutting regression testing time before each release
- Catching bugs before they reach staging or production
- Enabling the team to release faster without sacrificing quality
- Freeing QA engineers for exploratory and higher-value testing
Goals should also define how you measure success, including test execution time and pass/fail rates.
Vague goals like "improve quality" produce vague outcomes. Specific goals produce specific metrics and support better overall software quality.
Step 2: decide what to automate
Not everything deserves automation, and not all tests remain good automation candidates. Use these criteria, and review testing scenarios and test cases with a prioritization framework based on complexity, stability, and impact:
| Criterion | Automate | Keep Manual |
|---|---|---|
| Test frequency | Runs every sprint or daily | Runs once or rarely |
| Stability | Steps are well-defined and stable | UI changes frequently |
| Data volume | Multiple datasets needed | Single scenario |
| Risk level | Business-critical flow | Edge case, low impact |
| Manual run time | Takes 30+ minutes | Takes 2 minutes |
High-value automation candidates: direct your automation effort toward critical tests that reduce human error and strengthen software quality.
- Smoke tests on every build
- Regression suites covering previously broken flows
- API contract tests between services
- Data validation across integrations
Low-value automation candidates:
- One-time migrations
- Highly visual UI checks requiring human judgment
- Exploratory testing that needs creative thinking
Step 3: set your test environment rules
Your tests are only as reliable as the environment they run in.
Key environment principles:
- Environments should mirror production as closely as possible
- Each test should set up and tear down its own data independently
- Tests should never share mutable state across runs
Do not copy production data directly unless it is anonymized to protect sensitive information; synthetic data is often a safer choice for automated tests.
Note: Shared test environments are one of the leading causes of flaky tests. When two tests compete for the same data or the same user account, results become unpredictable. Isolate your data at the test level whenever possible, and use disciplined test data management to maintain efficiency and improve test efficiency.
Flaky test detection is much harder when your environment is the actual problem. Fix the environment first, then investigate the test code.
TestDino's flaky test detection automatically distinguishes environment-caused failures from genuine code regressions, saving hours of guesswork on every CI run.
Step 4: choose your framework type
Before picking a specific tool, decide what kind of framework fits your team:
- Data-driven -- use data-driven testing when you need to run the same flow across many inputs by separating test data from test scripts
- Page Object Model (POM) -- if your team writes UI tests and wants maintainable selectors; the Page Object Model stores HTML elements in separate files to improve maintainability
- BDD -- if product managers or non-engineers need to understand test scenarios
- Modular -- if you want shared components reused across multiple test suites
Framework decisions should also define how test automation scripts are versioned, reviewed, and registered under source control.
Playwright's page object model is a clean example of how modular architecture keeps test code organized as the suite scales.
Step 5: define your maintenance plan
A test suite without a maintenance plan is a liability, not an asset, so maintenance needs clear ownership across the testing team.
QA leads usually set priorities and report outcomes to stakeholders, while QA engineers increasingly transition into test designers rather than working only as manual testers, and automation engineers typically handle the more complex framework and integration work.
Set a schedule for:
- Regular review of flaky tests (weekly or per sprint)
- Deprecating tests that no longer reflect current behavior
- Updating selectors when the UI ships changes
- Reviewing coverage gaps after each release cycle
Larger organizations may use a QA Center of Excellence to define standards and manage tooling
Flaky test analysis is something teams should do continuously, not reactively after the suite breaks completely.
Choosing the right automation tools and framework
Tool selection is where most teams spend too much time debating and too little time aligning.
The right rule: pick a test automation tool that fits your existing tech stack, your team's preferred** programming languages, and current skill set, not just the most popular one.
Most modern web testing tools share similar core capabilities. The differences that actually matter for your test automation strategy come down to:
- Native parallel execution support
- Built-in tracing and debugging tools
- CI/CD integration quality
- How well automated testing tools fit your pipeline and broader tech stack
Here is a general overview of commonly used web test automation tools:
| Tool | Language Support | Native Parallel Execution | Built-in Tracing | Best For |
|---|---|---|---|---|
| Playwright | JS/TS, Python, Java, C# | Yes (native sharding) | Modern web apps, cross-browser | |
| Cypress | JS/TS | Available through Cypress Cloud recording/CI parallelization; plan limits apply. | Component and integration testing | |
| Selenium | Most major languages | Yes (Grid) | No (third-party) | Legacy or multi-language teams |
| WebdriverIO | JS/TS | Node.js ecosystem |
The wrong tools can create integration issues and higher maintenance costs.
Tip: Evaluate tools against your real pipeline constraints before committing. The Playwright vs Cypress comparison covers the practical trade-offs that matter for scaling teams.
If you are migrating from an older stack, the Selenium to Playwright migration guide walks through the exact steps involved in moving a production suite. Newer AI-native platforms can reduce maintenance by 85-95%, and composable test libraries can cut automation setup from 1,000 hours to 60 hours when they genuinely fit the team's workflow.
Framework architecture decisions
Once you have a tool, structure matters. A good Playwright framework setup should also support active development so tests can evolve with changing features. It includes:
- A clear folder structure separating tests, fixtures, and utilities
- A shared authentication mechanism so tests do not re-login for every case
- Environment-specific configuration (local, staging, production) that fits software development workflows and pipeline integration needs
- A CI-ready runner config with parallelism enabled
import { defineConfig } from '@playwright/test';
export default defineConfig({
  testDir: './tests',
  fullyParallel: true,
  retries: process.env.CI ? 2 : 0,
  workers: process.env.CI ? 4 : undefined,
  reporter: 'html',
  use: {
    baseURL: process.env.BASE_URL || 'http://localhost:3000',
    trace: 'on-first-retry',
  },
});
This base configuration enables parallel workers on CI, captures traces on retry so failures are debuggable, and reads the base URL from an environment variable.
Playwright best practices goes deeper on locator strategies, wait patterns, and test isolation that keeps your suite stable long-term.
CI/CD integration and continuous testing
A test automation strategy that does not run automatically on every code change is not really a strategy. It is a manual chore with extra steps.
The goal of pipeline integration is a simple loop built for rapid feedback:
Code pushed, Tests triggered, Results surfaced, Engineers notified
The faster and more reliable that loop is, the more useful your automation becomes.
Continuous testing is the practice of running automated tests at every stage of the software delivery pipeline, from a developer's pull request all the way to production monitoring. The goal is to shrink the feedback loop between writing code and knowing it works. Effective CI/CD uses multiple test stages for earlier problem detection and treats quality as a shared team metric, not just a QA responsibility.
Setting up Playwright in GitHub Actions
name: Playwright Tests
on:
  push:
    branches: [main, develop]
  pull_request:
    branches: [main]
jobs:
  test:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with:
          node-version: '20'
      - name: Install dependencies
        run: npm ci
      - name: Install Playwright browsers
        run: npx playwright install --with-deps
      - name: Run Playwright tests
        run: npx playwright test
      - name: Upload report
        uses: actions/upload-artifact@v4
        if: always()
        with:
          name: playwright-report
          path: playwright-report/
          retention-days: 30
This workflow triggers on every push and pull request. The report uploads as an artifact so the team reviews failures without re-running locally.
Full guidance on Playwright in GitHub Actions covers sharding, caching browsers, and optimizing runner costs.
Shift-left: catch bugs earlier
Shift-left means moving testing earlier in the development cycle. Instead of running the full regression suite only before a release, you run targeted tests on every PR.
This works best when teams set clear criteria for when a user story is considered done and define the Definition of Done to include automated tests in the overall testing process.
Research consistently shows that defects found during development cost significantly less to fix than those found in production. The multiplier varies by system complexity, but the directional finding is consistent across industry reports from sources including IBM and NIST.
Playwright PR health checks shows how to gate merges on test results so risky code never reaches main without passing a minimum suite and meeting clear done criteria.

Metrics that prove your strategy is working
You cannot improve what you do not measure. A test automation strategy needs clear success metrics from day one to measure success and prove business value.
Avoid vanity metrics like "total tests automated." Track metrics that reflect actual business impact, with success metrics tied to overall software quality rather than activity alone:
| Metric | What It Measures | Why It Matters |
|---|---|---|
| Defect escape rate | % of bugs reaching production vs. caught in testing | Measures real effectiveness of your test coverage |
| Regression time saved | Hours saved per release cycle vs. manual testing | Quantifies ROI for leadership conversations |
| Test flakiness rate | % of tests producing inconsistent results | Indicates health of your suite architecture and broader testing efforts |
| Mean Time to Detect (MTTD) | How fast a failing test surfaces after a bad commit | Measures speed of your feedback loop |
| CI pass rate | % of pipeline runs passing on first attempt | Overall reliability signal for the suite |
Playwright reporting metrics breaks down how to extract these numbers from Playwright's built-in reporter and external dashboards.
For teams who need to present test data to non-technical stakeholders, flaky test reports for non-technical stakeholders provides templates and framing for making results legible to leadership.
TestDino goes beyond raw reporting. It tracks all of these metrics automatically across every CI run, surfaces trend lines, and highlights when a metric starts drifting before it becomes a real problem.
The ROI reality check
Industry data shows that mature automation strategies typically deliver 300-500% return over a three-year period, with break-even occurring within 6-13 months on average. But these numbers depend heavily on two factors:
- Maintenance cost control. Well-structured suites spend 10-25% of effort on maintenance. Brittle suites can spend 60-70%, erasing any ROI.
- CI/CD integration depth. Automation that runs in a silo does not produce the speed improvements the data is based on.

Note: The ROI curve above is a directional reference based on industry aggregate benchmarks. Actual results vary significantly based on suite size, tool choice, team structure, and CI/CD maturity. Do not use this as a guaranteed projection.
Test reporting tools covers how to set up dashboards that surface these metrics automatically, so you are not calculating them manually each sprint.

The future of test automation strategy
The core principles of a good test automation strategy have not changed: define goals, choose the right scope, maintain your suite, and integrate into CI. What has changed is the tooling available to support those principles.
AI-assisted test generation
AI coding tools are now capable of helping teams design tests from user stories, component code, or existing API specs, not just generate scaffolding. This does not replace strategic thinking, but it lowers the time cost of initial test creation, even though understanding user behavior still matters when reviewing AI-generated tests.
How to test AI-generated code is an increasingly relevant concern. When AI writes application code, the tests validating it need to be written and reviewed by humans who understand the intent.
Self-healing tests
Self-healing locators use AI, with self healing capabilities that update selectors automatically, to detect when a UI element has changed and automatically update the selector. This directly addresses one of the biggest maintenance burdens in any test automation strategy.
The Playwright AI ecosystem covers how MCP integrations, agentic tools, and self-healing patterns are changing what a modern test automation strategy looks like in practice.
Agentic test intelligence
The shift from test reporting to AI-native test intelligence is one of the most significant changes happening in QA right now.
Instead of looking at a report and manually deciding what broke and why, intelligent platforms correlate failures, identify root causes, and surface patterns across CI runs. TestDino is built around this principle: every test result is automatically analyzed, categorized, and surfaced with context so engineers spend zero time on triage.
Agentic testing tools compared gives a detailed look at which platforms are genuinely delivering on this promise versus those that are simply adding "AI" branding to existing features.
Tip: Before adopting any AI-powered testing feature, evaluate it against your real maintenance pain points. Self-healing is genuinely valuable for UI-heavy suites. AI test generation helps most with boilerplate-heavy scenarios. Neither replaces strategic thinking about what to test and why.
The state of automation report documents how teams across different maturity levels are incorporating AI into their existing strategies, with honest assessments of what is delivering value today versus what is still emerging.
Conclusion
A test automation strategy is not a document you write once and forget. It is a set of living decisions: what to test, how to structure it, where it runs, and how you measure whether it is working.
The teams that get the most out of automation treat test code as seriously as product code. They build it with architecture in mind, measure outcomes rather than activity, and integrate it so deeply into their delivery pipeline that nobody has to think about "running tests" as a separate step.
Start with the test pyramid. Define your goals before you touch a tool. Pick tooling that fits your stack. Connect it to CI from day one. Measure what matters.
That is what a real test automation strategy looks like, and it is how you go from a suite nobody trusts to one that gives your whole team release confidence on every push.
For teams using Playwright automation as their primary tool, the Playwright test management guide covers how to organize, track, and scale your suite as your strategy matures.
FAQs
Ayush Mania
Forward Development Engineer